
Enzonix
Shared Compute - General Compute
$5.00/mo
1 vCPU · 1 GB · 20 GB
Choose location
Ashburn, United States
| Provider | Plan | vCPU | RAM | Disk | Regions | Billing | Price |
|---|---|---|---|---|---|---|---|
| Enzonix | Shared Compute - General Compute | 1 | 1 GB | 20 GB | Ashburn, United States | Fixed price | $5.00/mo |
| Enzonix | Shared Compute - General Compute | 1 | 1 GB | 20 GB | Amsterdam, Netherlands | Fixed price | $5.00/mo |
| Enzonix | Shared Compute - General Compute | 2 | 4 GB | 80 GB | Amsterdam, Netherlands | Fixed price | $9.00/mo |
| Enzonix | Shared Compute - General Compute | 2 | 4 GB | 80 GB | Ashburn, United States | Fixed price | $9.00/mo |
| Enzonix | Shared Compute - General Compute | 4 | 8 GB | 160 GB | Amsterdam, Netherlands | Fixed price | $16.00/mo |
| Enzonix | Shared Compute - General Compute | 4 | 8 GB | 160 GB | Ashburn, United States | Fixed price | $16.00/mo |
| Enzonix | Shared Compute - General Compute | 8 | 16 GB | 320 GB | Amsterdam, Netherlands | Fixed price | $32.00/mo |
| Enzonix | Shared Compute - General Compute | 8 | 16 GB | 320 GB | Ashburn, United States | Fixed price | $32.00/mo |
| Enzonix | Shared Compute - General Compute | 1 | 1 GB | 20 GB | Ashburn, United States | Hourly | $0.007/hr |
| Enzonix | Shared Compute - General Compute | 1 | 2 GB | 40 GB | Ashburn, United States | Hourly | $0.01/hr |
| Enzonix | Shared Compute - General Compute | 2 | 4 GB | 80 GB | Ashburn, United States | Hourly | $0.015/hr |
| Virtualized | Shared Compute - General Compute | 2 | 4 GB | 40 GB | Phoenix, United States | Fixed price | $12.49/mo |
| Virtualized | Shared Compute - General Compute | 3 | 6 GB | 60 GB | Phoenix, United States | Fixed price | $17.49/mo |
| Virtualized | Shared Compute - General Compute | 4 | 8 GB | 80 GB | Phoenix, United States | Fixed price | $22.99/mo |
| Virtualized | Shared Compute - General Compute | 8 | 16 GB | 160 GB | Phoenix, United States | Fixed price | $44.99/mo |
| Virtualized | Shared Compute - General Compute | 16 | 32 GB | 320 GB | Phoenix, United States | Fixed price | $79.99/mo |
| Virtualized | Shared Compute - General Compute | 32 | 64 GB | 640 GB | Phoenix, United States | Fixed price | $139.99/mo |
OpenClaw Instant App
OpenClaw is a personal AI assistant gateway that stays online on your own server. Compare live VPS prices, CPU, RAM, disk and regions, launch OpenClaw on the plan you choose, and keep root access.
OpenClaw
Instant App on marketplace VPS
Live marketplace offers
Choose billing and size, compare providers side by side, pick a location, then launch.
Shared Compute - General Compute
$5.00/mo
1 vCPU · 1 GB · 20 GB
Choose location
Ashburn, United States
1 provider
OpenClaw runs a Gateway that owns sessions, channels, memory and workspace on a Linux VPS. Use cloud model APIs for everyday chat, connect messaging apps when you are ready, and open the Control UI from your laptop or phone.
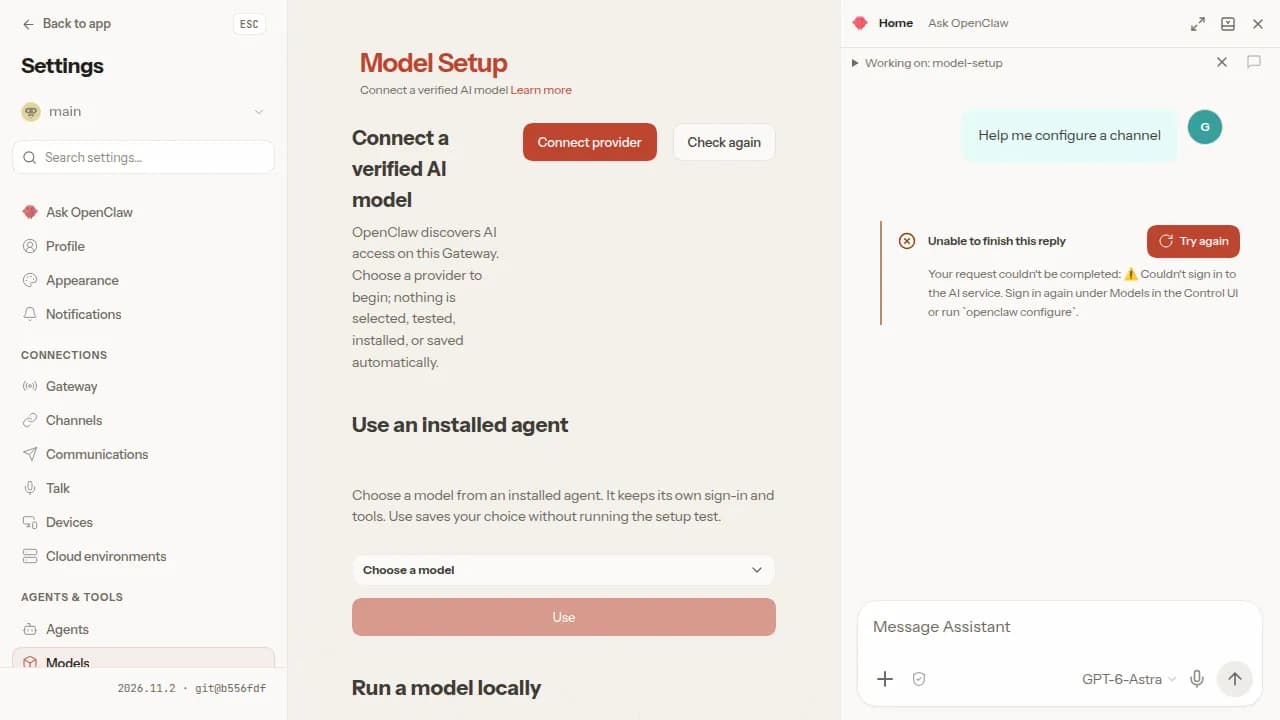
Leave the Gateway running on the VPS so the assistant stays available while your laptop sleeps. State and workspace stay on the server you control.
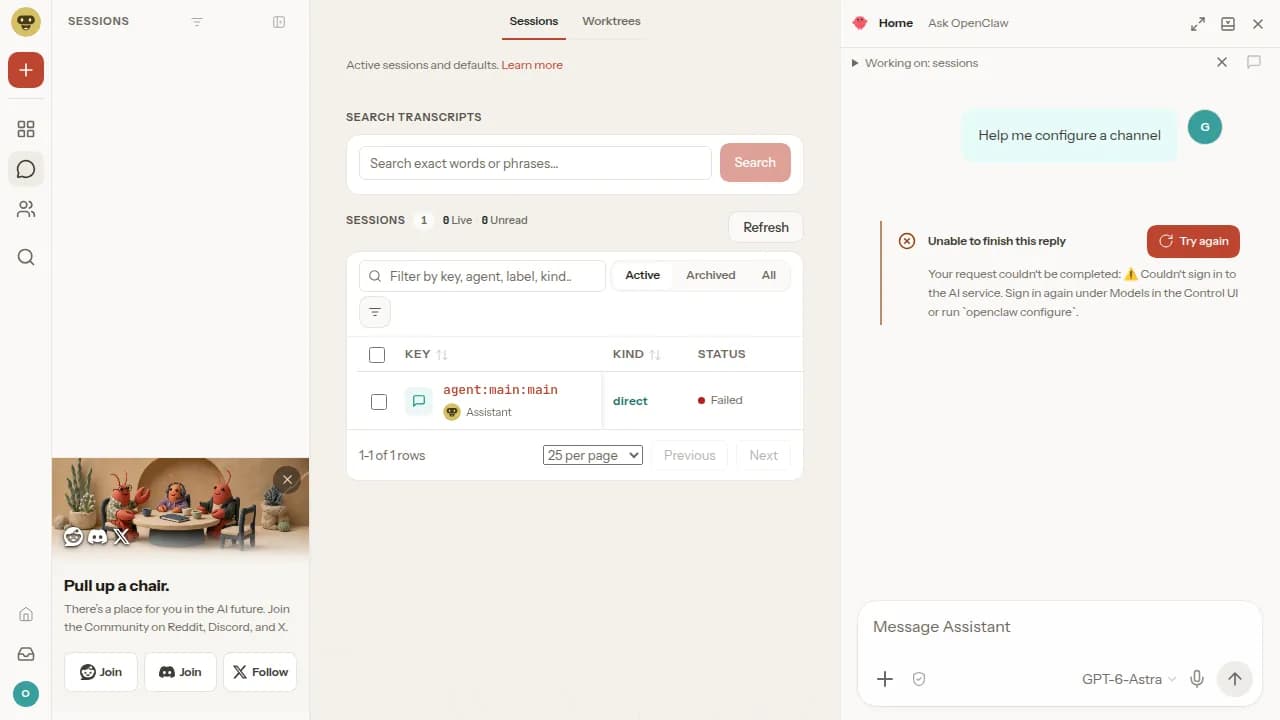
After the server is ready, open the Control UI and sign in with the gateway token from your server notes. Finish models and channels there at your pace.
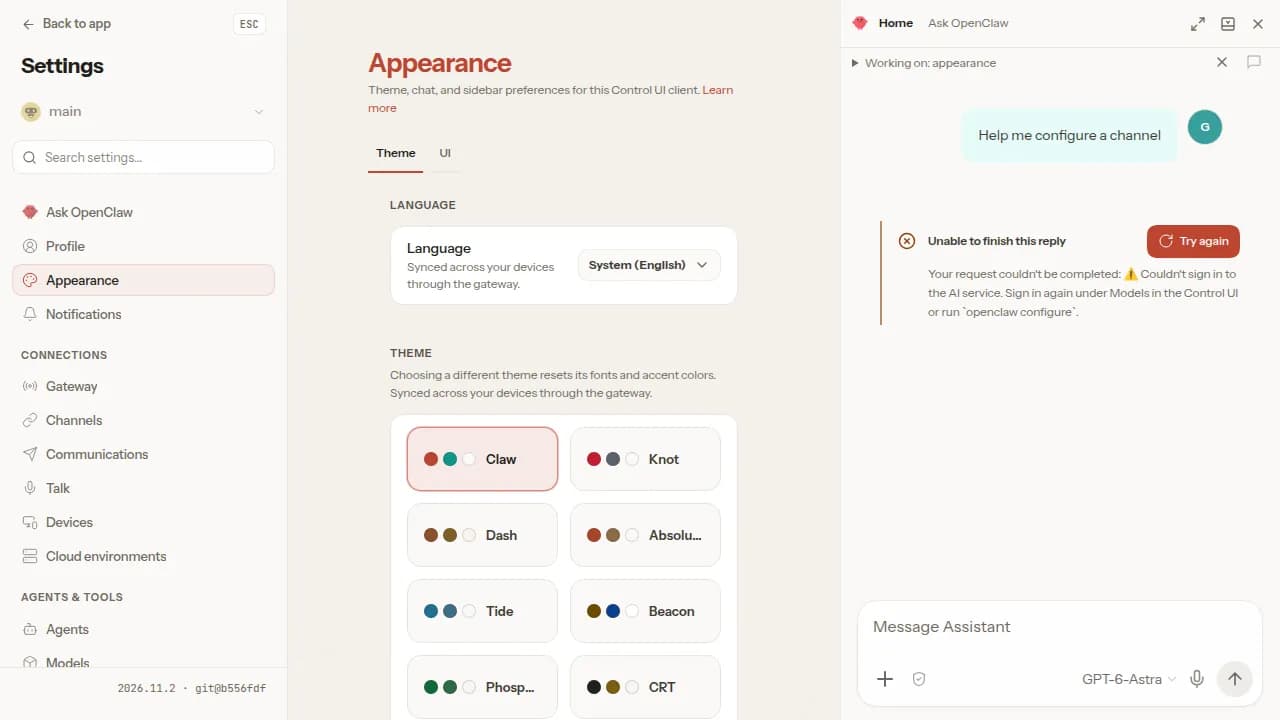
Connect chat channels and OpenAI-compatible or other model providers when you want. Domain and inference API key fields at create time are optional and can stay empty.
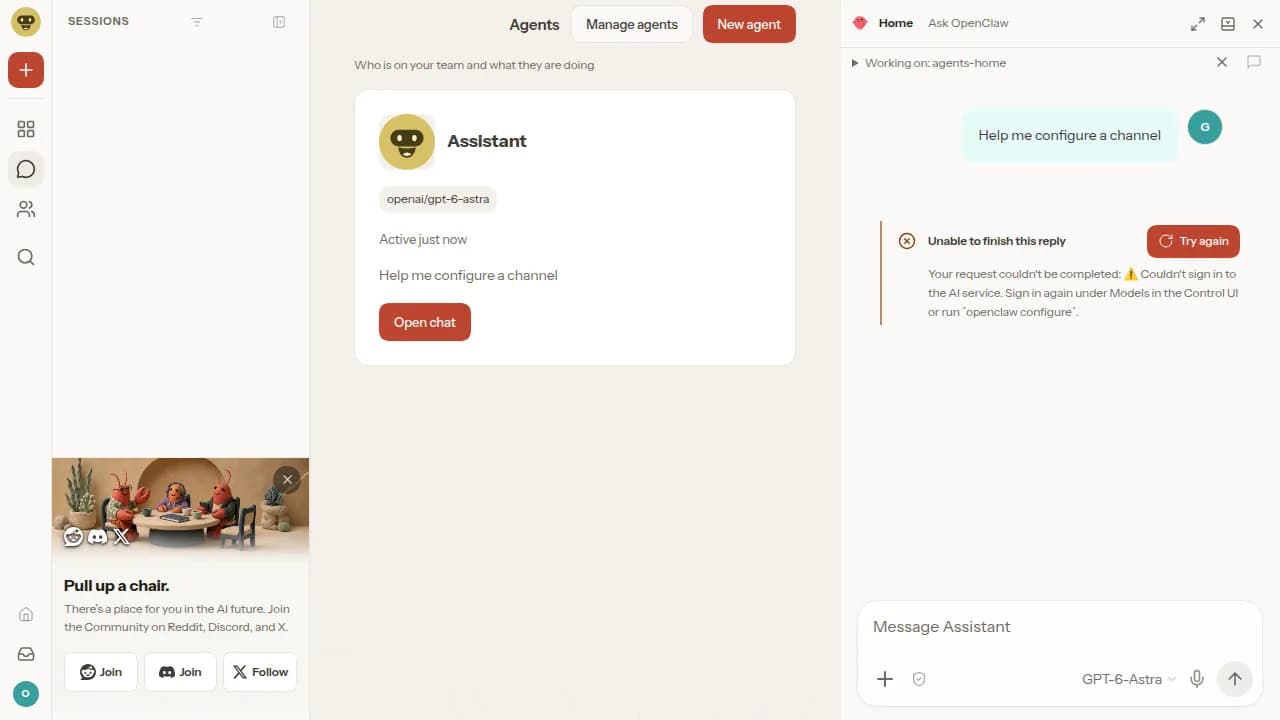
Config, agents and workspace files live on the VPS under root access. Back them up like any other self-hosted service.
Compare live OpenClaw VPS plans from independent providers, then self-host an always-on OpenClaw gateway on the offer you pick.
See live prices, regions and plan sizes before you buy. Shop across independent providers instead of one hoster’s catalogue.
Pick a plan and OpenClaw is prepared on that VPS for you. You still get a real server with root access when you want to harden or extend it.
Compatible offers list cities and countries. Put the gateway nearer the people and tools that message it, including WhatsApp, Telegram and other channels you connect later.
Sessions, workspace and config live on your VPS. You control SSH, tokens, model keys and how the Control UI is reached.
Most OpenClaw hosting pages sell one company’s servers. NodeRings lists Compute Instance plans from independent providers so you can compare OpenClaw-ready VPS offers by price, size and region, then launch on the one that fits.
OpenClaw Instant App prepares the gateway on the provider VPS you selected. NodeRings does not operate that hardware or sell its own VPS fleet.
Compare plans, pick a provider offer, and launch OpenClaw on that server.
01
Browse live offers below. Every general-compute plan is listed — pick the size you want. Sort by provider, size, price and region the way you would for any production VPS.
02
Choose the provider plan. Domain and inference API key are optional. Leave them blank if you prefer to add models and DNS after the server is up.
03
Confirm checkout, wait for the VPS, then open the Control UI with the gateway token from your server notes. You keep root SSH.
With cloud model APIs the Gateway is fairly light. Browser tools, media, many channels and large workspaces raise RAM and disk. Official guides often start around 1 to 2 GB for quiet text use; leave more room for Docker and growth when you pick a plan.
| Workload | Illustrative starting point | Note |
|---|---|---|
| Cloud models, light personal use | 2 vCPU / 4 GB RAM / 40+ GB disk | Suggested start for a quiet always-on gateway. |
| Several messaging channels | 2 to 4 vCPU / 4 to 8 GB RAM | Extra headroom for concurrent sessions, logs and media. |
| Browser tools or heavier automation | 4 vCPU / 8 GB RAM | Web tooling and larger context windows need more memory. |
| Busy shared or production gateway | Often 4+ vCPU / 8 to 16 GB RAM and more disk | Size for traffic, workspace growth and backups. No universal session count. |
These are starting points, not guarantees. Needs depend on models, channels, tools and how long the Gateway keeps history on disk.
This is self-hosted OpenClaw on a provider VPS, not managed AI hosting. You pick the plan. The gateway is prepared on that server. Day-to-day agent care stays with you.
OpenClaw is prepared and a gateway token is created for you. Sign in to the Control UI with the token from the VPS.
Root SSH on the VPS. You own DNS, TLS, Tailscale or tunnel access, model spend, channel tokens, OS updates and backups unless a provider product says otherwise.
Managed model billing, automatic channel onboarding and hands-off OS patching are not bundled in. Complete those in OpenClaw and on the server after it is up.
NodeRings helps with marketplace, billing and console. Provider hardware issues go to that provider. Looking after OpenClaw on the server is yours.
OpenClaw is a self-hosted personal AI assistant. A Gateway on your server owns sessions, channels, memory and workspace. You talk to it from the Control UI or from messaging apps you connect later.
A VPS stays online when your laptop sleeps. Official docs treat a Linux cloud VPS as a normal place to run an always-on Gateway, with the Control UI reached over SSH, Tailscale or another private path you choose.
No. NodeRings is a marketplace. Independent providers list VPS plans. You pick a plan, OpenClaw is prepared on that provider server, and you manage the gateway from there.
No. You get a virtual machine with OpenClaw prepared for you, plus root access. That is different from a fully managed single-hoster product that owns updates and support for you. Domain DNS, model keys, backups and day-to-day care remain yours unless a provider product says otherwise.
It prepares the OpenClaw gateway on the VPS you choose so you skip hunting through install guides by hand. It is still your self-hosted server, not a separate managed hosting brand.
Yes. Channel setup happens in OpenClaw after the Gateway is up. This Instant App does not require channel tokens at create time.
Not for normal cloud-model use. The Gateway calls remote model APIs. Local model inference is a different sizing problem and usually wants a GPU host.
A common starting point is about 2 vCPU, 4 GB RAM and 40 GB disk. Quiet cloud-model use can work on less; browser tools, many channels and growing workspaces usually need more. Use the sizing guide above and compare plans in the list.
You confirm the plan and finish checkout. When the server is ready, open the Control UI and sign in with the gateway token from your server notes. Keep that token private.
Yes. Each compatible plan lists available regions. Pick the city or country that matches latency and compliance needs.
You do, unless you add backup tooling yourself or a provider product explicitly includes it. Treat the VPS state and workspace as the source of truth and back them up regularly.
You can move to a larger plan from the same or another marketplace provider when load grows. Exact options depend on the provider. Compare offers again when you need more capacity.