
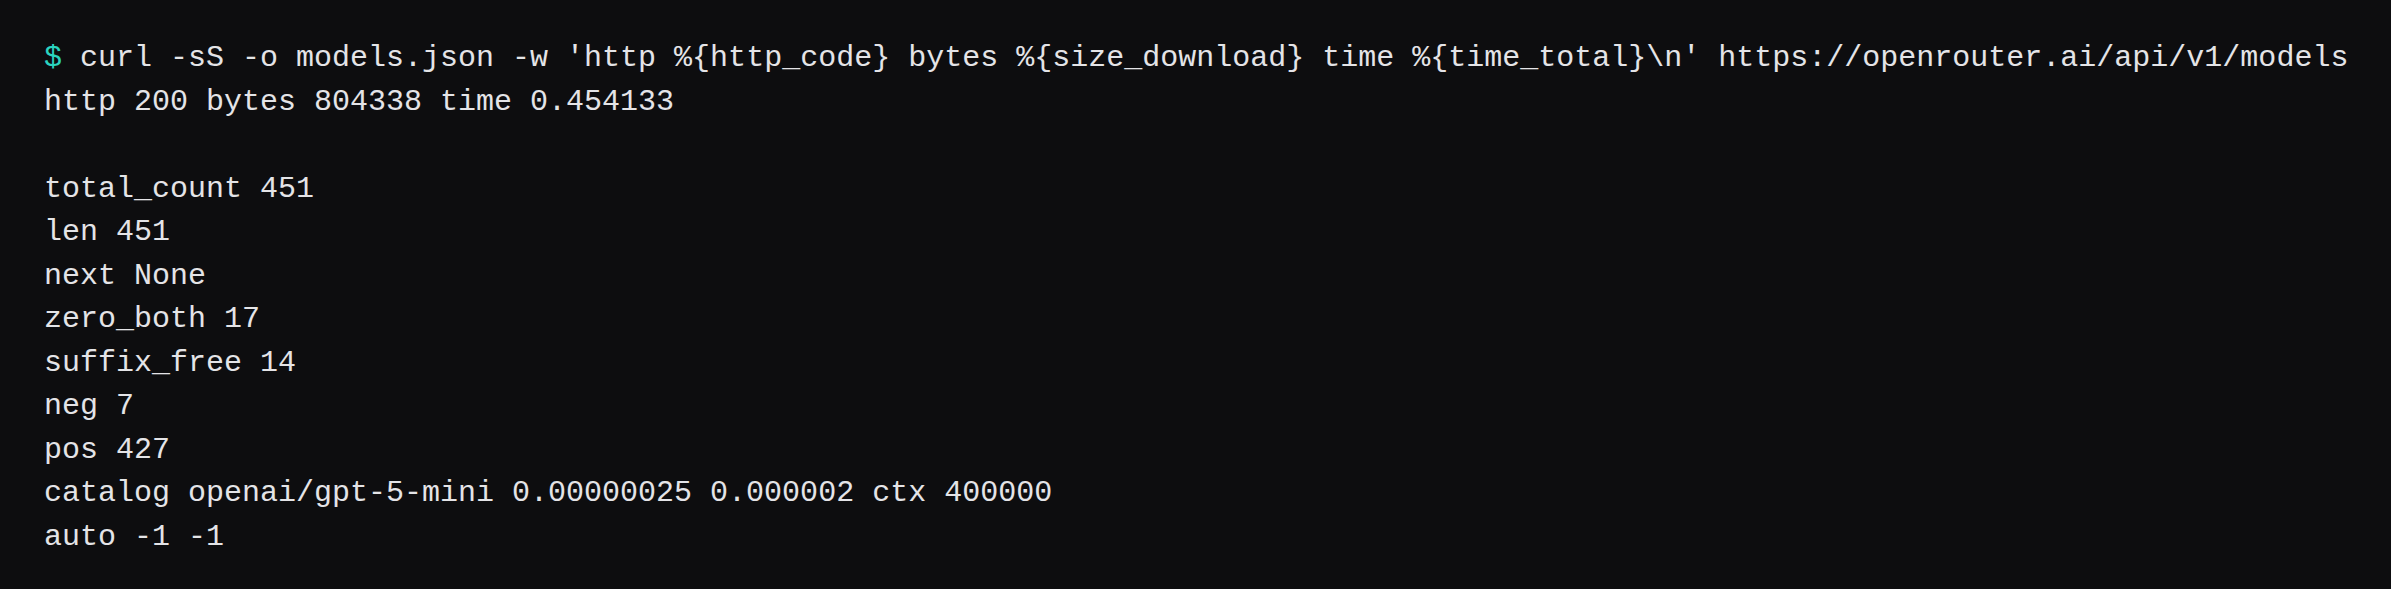
OpenRouter's models list, fetched from this guest, came back HTTP 200 in 0.454133 seconds and 804,338 bytes. total_count was 451, links.next was null, and the array length was 451. openai/gpt-5-mini is posted at 0.00000025 dollars per prompt token and 0.000002 per completion token. The models schema calls those fields USD per token, so multiplying by 1,000,000 makes them $0.25 and $2 per million tokens. The endpoints route for that same id returned four prices. OpenAI flex is half the catalog pair. Azure's azure/swedencentral tag is 1.1 times it. A completion with the auth header left off came back HTTP 401, No cookie auth credentials found, in 0.194525 seconds. The same body with Authorization: Bearer sk-or-v1-example came back HTTP 401, User not found., in 0.321511 seconds.
The pricing page says inference is billed at the provider's list price on every plan, and that OpenRouter's fee is charged when you buy credits, 5.5% on Standard and 8% on Business. 5.5% of a $100 Standard purchase is $5.50. 8% of that purchase is $8.
The guest was Ubuntu 24.04.5, kernel 6.8.0-147-generic, qemu -m 1024 -smp 1, MemTotal 984,552 kB, SwapTotal 0. /usr/bin/time -v put the models curl at a maximum resident set size of 14,080 kB and a wall time of 0:00.48. curl itself exited 0 on the 401s, because the command had no -f. The HTTP status is the line in the figure.
| From this guest | |
|---|---|
| Models list | HTTP 200, 804,338 bytes, total_count 451, 0.454133 seconds |
gpt-5-mini catalog | $0.25 per million prompt tokens, $2 per million completion tokens |
| Endpoints | four prices, flex at half, Sweden Central at 1.1 times, discount 0 |
| Completion | HTTP 401 with the header off, HTTP 401 with sk-or-v1-example |
| Standard fee | 5.5% of the credit purchase. 5.5% of $100 is $5.50 |
| Guest RAM | MemTotal 984,552 kB. The models curl peaked at 14,080 kB |
What did the models list return?
Fourteen ids end in :free. Seventeen ids have a prompt price of 0 and a completion price of 0. The three zero-price ids that do not end in :free are google/lyria-3-pro-preview, google/lyria-3-clip-preview, and openrouter/free. Four hundred twenty-seven ids have a prompt price above 0. Seven ids have a prompt price of -1 and a completion price of -1: typesafe/jev-router, nvidia/switchyard, openrouter/auto-beta, openrouter/fusion, openrouter/pareto-code, openrouter/bodybuilder, and openrouter/auto.
The pricing page says Standard includes 600+ models and 25+ free models, and the Free column says 4 free providers. The list I fetched is the public GET /api/v1/models payload, with links.next null. Those two counts are the page's and the response's.
openrouter/auto is one of the -1 ids. The same pricing page says routing through openrouter/auto adds no fee, and you pay the rate of whichever model serves the request. The -1 in this run is that field on the list.
What do the four gpt-5-mini endpoints charge?
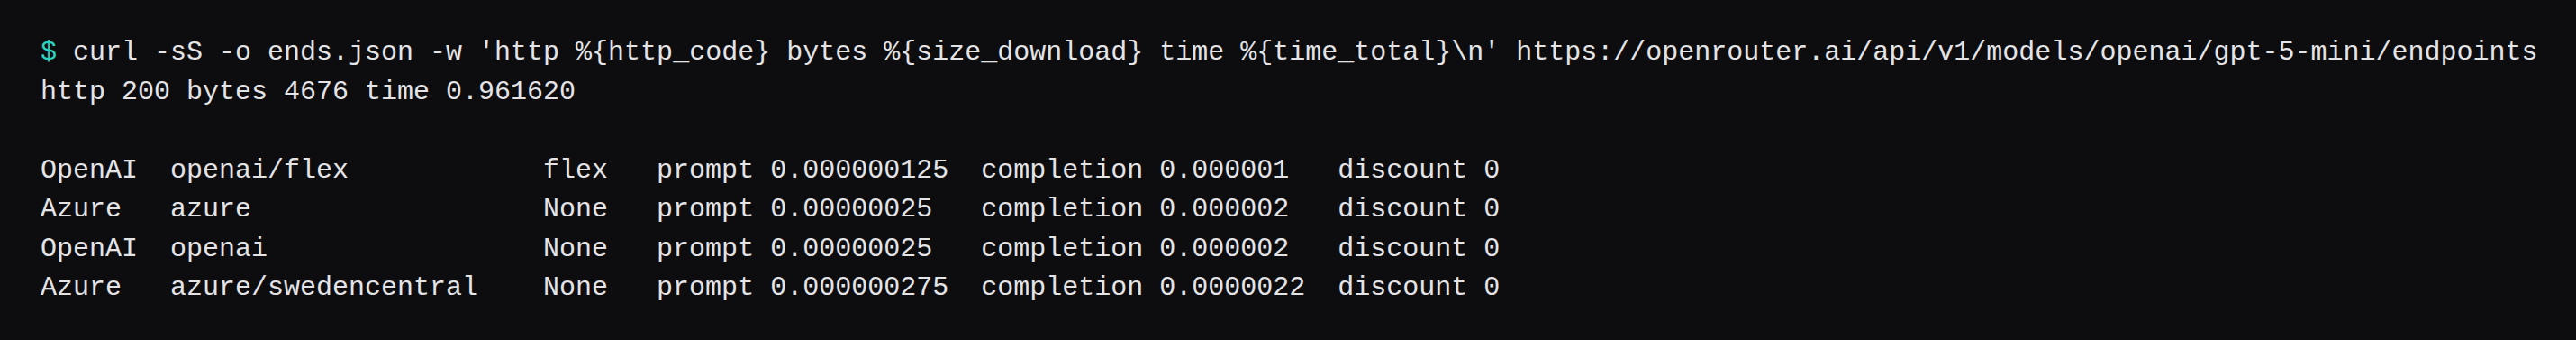
GET /api/v1/models/openai/gpt-5-mini/endpoints came back HTTP 200, 4,676 bytes, in 0.961620 seconds. /usr/bin/time -v recorded a wall time of 0:00.96 and a maximum resident set size of 14,208 kB. Four endpoints, in the order the JSON listed them:
| Provider | Tag | Tier | Prompt, USD per token | Per million | Completion, USD per token | Per million |
|---|---|---|---|---|---|---|
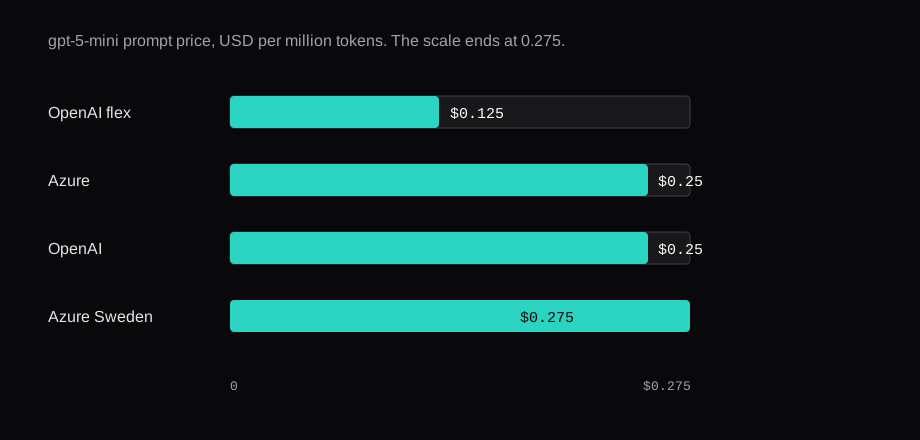
| OpenAI | openai/flex | flex | 0.000000125 | $0.125 | 0.000001 | $1 |
| Azure | azure | none | 0.00000025 | $0.25 | 0.000002 | $2 |
| OpenAI | openai | none | 0.00000025 | $0.25 | 0.000002 | $2 |
| Azure | azure/swedencentral | none | 0.000000275 | $0.275 | 0.0000022 | $2.20 |
0.000000125 × 2 = 0.00000025, and 0.000001 × 2 = 0.000002, so flex is half the catalog pair. 0.00000025 × 1.1 = 0.000000275, and 0.000002 × 1.1 = 0.0000022, so the Sweden Central tag is 1.1 times the catalog pair. Every endpoint's discount field was 0. The flex price is a different posted rate. The discount field did not produce it. The catalog strings match the OpenAI row and the Azure row whose tag is azure. Context length on the model object was 400,000.
Where does the 5.5% land?
The pricing page's fee row is N/A on Free, 5.5% on Standard, 8% on Business, and "Fee discounts available" on Enterprise. The FAQ on that page says the fee is charged when you buy credits, and the model token prices are the same on every plan. Standard and Business buy credits, by hand or with auto top-up, and each request deducts its cost from the balance. The page also says Enterprise can discount the OpenRouter fee, and that inference is not discounted.
The $5.50 and the $8 are 5.5% and 8% of a $100 purchase, which is the arithmetic of the percentages on the page.
BYOK, on that same page, is the provider billing you for inference directly. Standard and Business include $25,000 of list-price inference a month through BYOK with no OpenRouter fee. Above that allowance, the page says OpenRouter charges 5% of what the same request would cost at list price on OpenRouter, deducted from your credits. The Free column's BYOK cell says no.
The page also says an attempt that errors is not charged for its model tokens, and that streaming is priced per token the same way a finished response is. Payment methods listed for Standard and Business are credit and debit cards, AliPay, and crypto in USDC. The page says prices are exclusive of tax.
What does a completion do without a working key?
The auth page at https://openrouter.ai/docs/api_reference/authentication.md says the API uses a bearer token, and the Python example sets base_url to https://openrouter.ai/api/v1. Both of my completion calls used https://openrouter.ai/api/v1/chat/completions and the model openai/gpt-5-mini. The first left Authorization off. The second sent Bearer sk-or-v1-example. Neither body was a completion.

That auth page says keys created during onboarding get a $100 credit limit and expire after 180 days, and it tells you to set a credit limit on a key because a key with no limit can spend the balance, including auto top-ups. I created no key, so that $100 limit is the page's rule.
What cap applies to a :free id?
The limits page at https://openrouter.ai/docs/api_reference/limits.md says a free model variant is an id ending in :free. Its table header is "Credits purchased (all time)". Under 10, the cap is 20 requests per minute and 50 per day. At 10 or more, it is 20 per minute and 1,000 per day. The pricing page's FAQ says the same shape: 20 per minute and 50 per day, rising to 1,000 per day once the account has bought at least $10 of credits. The Free column on the pricing table says 50 requests a day. Standard's rate-limit cell says "Passthrough from the provider(s)".
The 14 :free ids are the ones that sentence names. openrouter/free and the two Lyria preview ids have price 0 and a different ending. I sent no :free completion, so the 20-per-minute cap stayed on the page.
What does the $5 VPS change?
RackNerd's specials page lists a 1 GB KVM VPS, 1 vCPU, 20 GB SSD, at $21.99 a year. Divided by 12, that is 1.8325, which is $1.83 a month. This guest was qemu -m 1024 -smp 1. The $5 is a ceiling for a box that size. The special is the price I could check. The guest placed the three requests. OpenRouter stayed on openrouter.ai.
The 5.5% is the Standard fee on a credit purchase for the OpenRouter account. AgentGateway on a $5 VPS is the guest that answered two model names from local mocks, with the provider key in a file on that machine. The base URL on OpenRouter's auth page is the baseUrl shape that post used. Pointing it at https://openrouter.ai/api/v1 sends the completion here, and the credit fee stays on the purchase. TensorFold on a $5 VPS is the local binary whose serve printed DriverUnavailable and left 8080 with no listener. This guest's three calls went to openrouter.ai.
Questions people ask about OpenRouter pricing
Does the token price include the 5.5%?
The pricing page says inference is billed at the provider's list price, and the 5.5% is charged when you buy credits on Standard. 5.5% of a $100 purchase is $5.50. The gpt-5-mini catalog strings are $0.25 and $2 per million tokens. Four endpoints post their own strings, and flex is half the catalog pair with discount 0.
Does openrouter/auto add a fee on top of the model?
The pricing page says routing through openrouter/auto adds no fee, and you pay the model that serves the request. In the models list that id's prompt and completion strings are -1. The completions on this guest used openai/gpt-5-mini.
Can I call the API with no key?
From this guest, leaving the header off returned HTTP 401 and No cookie auth credentials found. Bearer sk-or-v1-example returned HTTP 401 and User not found. The models list and the endpoints list both returned HTTP 200 with no key.
How many free models are there?
The pricing page says 25+ free models. The payload had 14 ids ending in :free and 17 ids with both token prices at 0. The limits page attaches the 20-per-minute and 50-per-day cap to the :free suffix.
Does a 1 GB VPS change the percentage?
The guest's models curl peaked at 14,080 kB on a MemTotal of 984,552 kB. The 5.5% is the Standard fee on a credit purchase, from the pricing page. The VPS in this run was the client that fetched the list.